Train once. Run a million calls.
Transcript
- 0:01
Every time you talk to an AI voice agent, something is guessing. A model reads a long prompt, thinks for a few seconds, and makes up an answer. Most days, it's right. A business can't run on most days.
- 0:17
Almost every voice agent today works the same way. Everything the caller says goes to a large language model, with a long prompt. That's three to four seconds of waiting, a bill on every turn of every call, and an answer that can change from one call to the next, because the model works on probability, not on rules.
- 0:39
We looked at voice agents through a different lens. A good call centre doesn't let new agents improvise. It trains them first, then puts them on the floor, where they handle thousands of calls the same way, every time. So we split the voice agent in two. A training centre, and a floor. Design time, and run time.
- 1:01
The training centre is DAKSH. DAKSH uses a language model once, the way a programmer uses a compiler. You describe the workflow, say, a bank's KYC check. DAKSH turns it into steps, rules, the many ways customers phrase each answer, in every language, and the replies, recorded in advance.
- 1:23
Nothing goes live unchecked. Every change DAKSH proposes is validated, then approved by a person. And when it's done, DAKSH steps away. There is no DAKSH at run time. Only the workflow it wrote.
- 1:37
The floor is the VARTA cognitive engine. Seven layers, each with one job. A reflex layer, for instant replies. Recognition, for names, numbers and dates. Routing, to pick the next branch. Rules, to decide. A voice layer, to speak. And an observer, watching the whole call.
- 1:59
And the language model? It's one layer of seven, and it goes last. VARTA asks it only when the rules can't decide. Even then, it picks from the branches the workflow allows. It cannot invent a route.
- 2:14
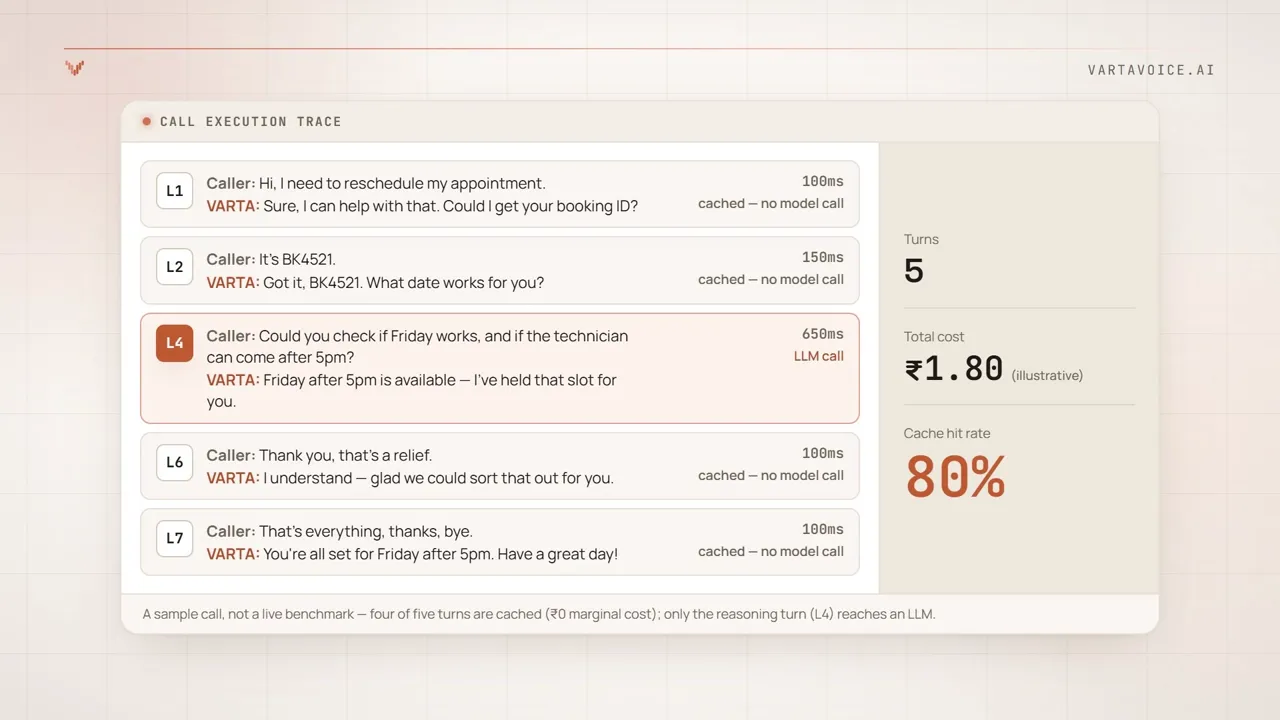
Rules decide in under two milliseconds, and the reply is audio prepared in advance, in the same voice. In our Bank KYC replay, eleven of thirteen customer turns never touched a language model.
- 2:28
So what does that give a business? Speed: no awkward pauses. Consistency: the same question gets the same approved answer, every time. Control: the rules are readable, so compliance can review them before a single call goes out.
- 2:46
And cost. The model is paid once, to build the workflow, not on every turn of every call. Modelled with our cost estimator, LLM spend falls by ninety-six to ninety-nine percent.
- 3:00
A bank asks its KYC questions in the same approved order and wording, on every call. An insurer confirms a policy number by rule, not by guesswork. A service company books a technician, without the caller waiting on a model.
- 3:16
A prompt is a wish. Probabilistic AI is brilliant at understanding and writing language, and that's exactly where we use it: to build. But a business process needs the same input to give the same output, an answer in milliseconds, and a record of why. You don't get that by asking a model nicely. You get it by compiling.
- 3:39
DAKSH trains it once. VARTA runs it a million times. Fast, predictable, and built for business.
About this film
Most voice agents ask a language model what to say on every turn of every call. VARTA splits the agent in two. At design time DAKSH, the training centre, uses an LLM once to write the workflow: steps, rules, the ways customers phrase each answer, and replies recorded in advance, each change validated and approved by a person. At run time the VARTA cognitive engine handles the call on seven layers, with the language model as one layer of seven, consulted last and limited to the branches the workflow allows. Rules decide in under two milliseconds, eleven of thirteen turns in the Bank KYC replay never reach a model, and LLM spend falls 96 to 99%, modelled with the site’s own cost estimator.
3:50 · · English captions
More films
Teaser · 56 s
The model can wait.
In a world where every voice agent waits for a model, one engine decided not to wait. Rules first, model last: seven layers, zero hesitation, the same voice at half the bill.
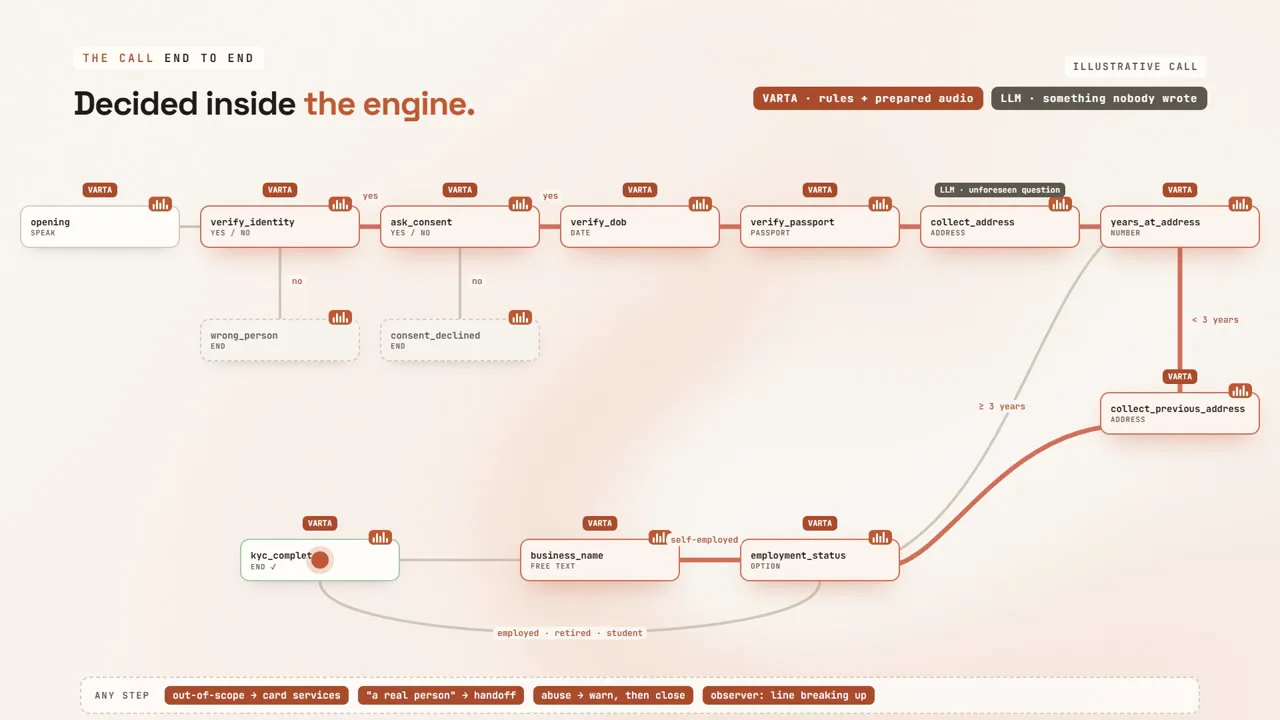
Walkthrough · 4 min
Configured once. Decided every turn.
Step by step through a bank KYC workflow: the configuration DAKSH writes at each step, and how it lets VARTA decide the call inside the engine instead of asking a language model.
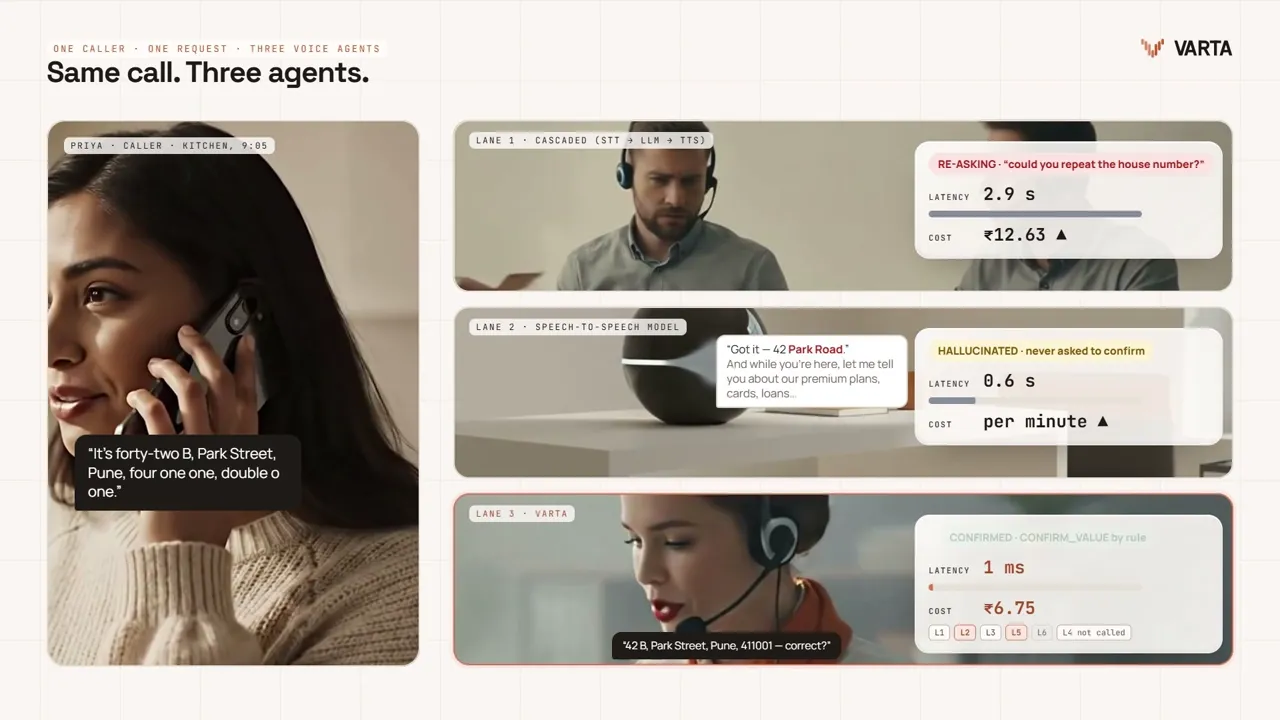
Head to head · 1 min
Same call. Three agents.
One caller, one request, three voice agents: a cascaded pipeline, a speech-to-speech model and VARTA. Watch which one waits, which one mishears the address, and which one confirms it by rule.
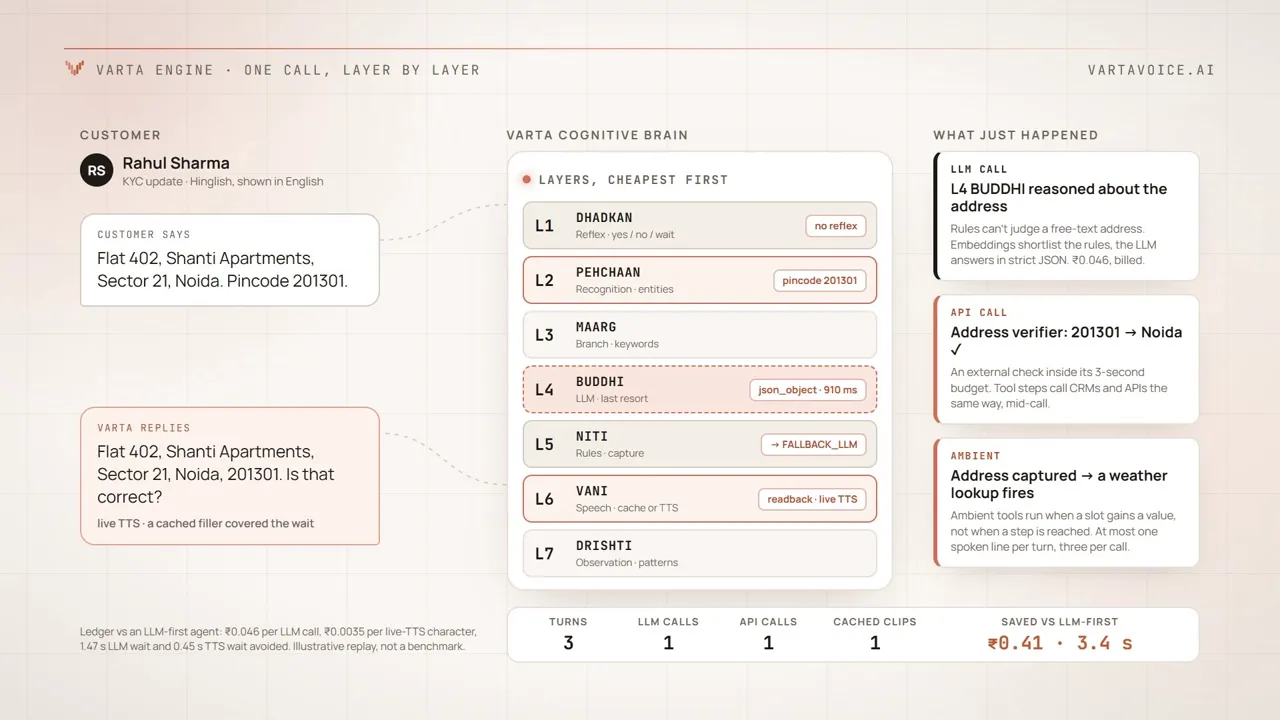
Inside the engine · 47 s
One sentence through the VARTA engine
Follow one caller sentence through VARTA layer by layer: reflex, recognition and rules first, an LLM only when nothing else can answer, every step on one visible ledger.
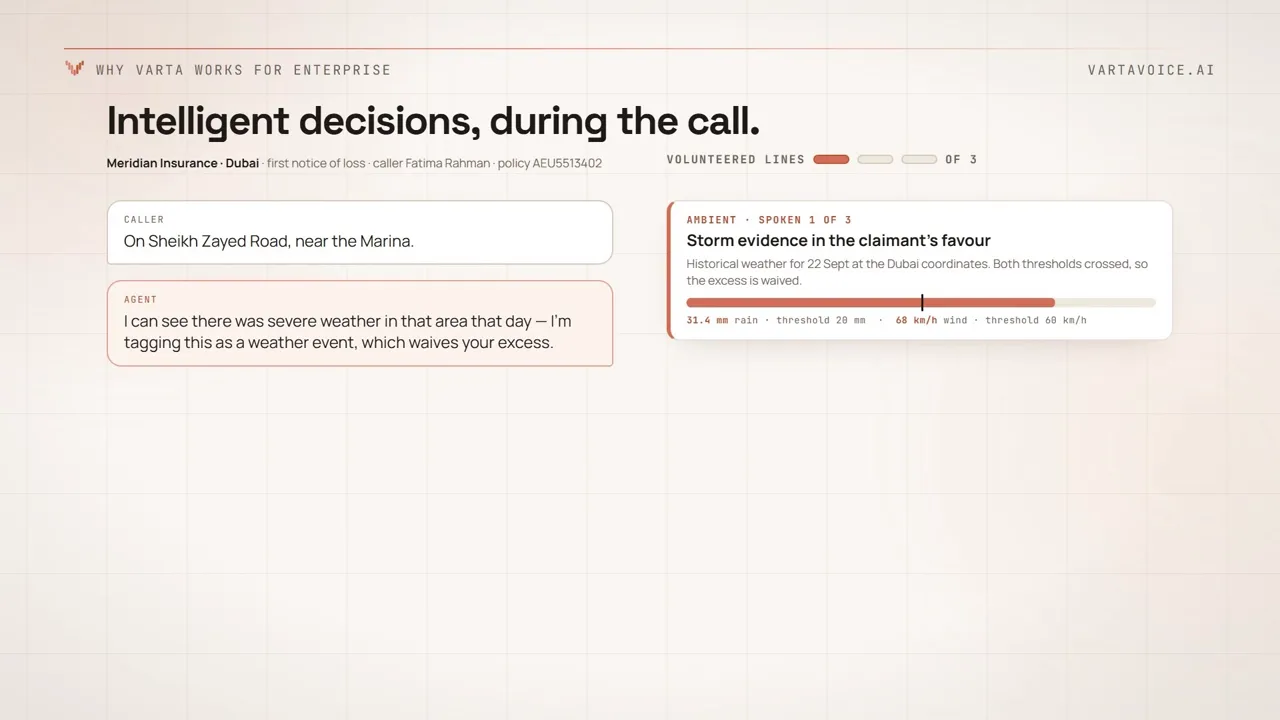
For enterprise · 1 min
Why VARTA works for enterprise
Fluency no longer closes deals. Decisions by rule, writes to your ERP mid-call, live data volunteered only when a threshold is crossed, and a deterministic cost engine, in four markets.
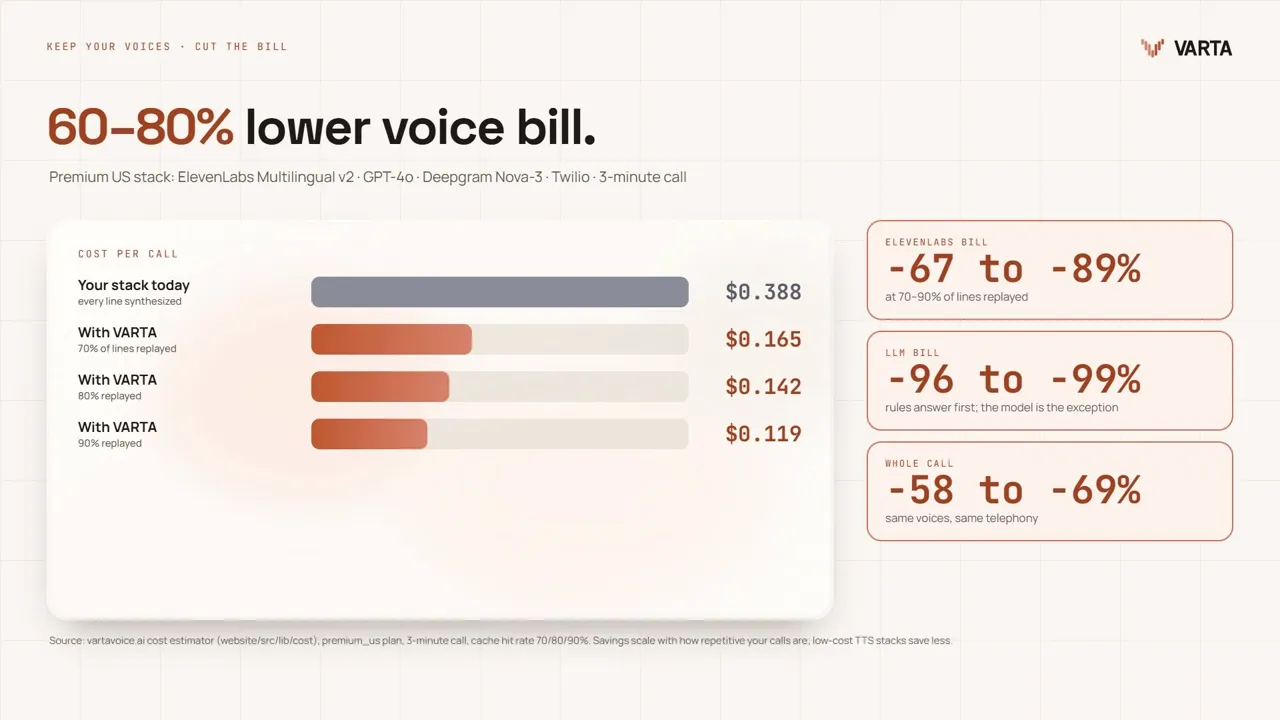
Premium voices · 1 min
Keep your voices. Cut the bill.
Keep the premium voice you chose. VARTA replays the lines an agent has said before from cache, in the same voice, and sends only the new ones to your provider.
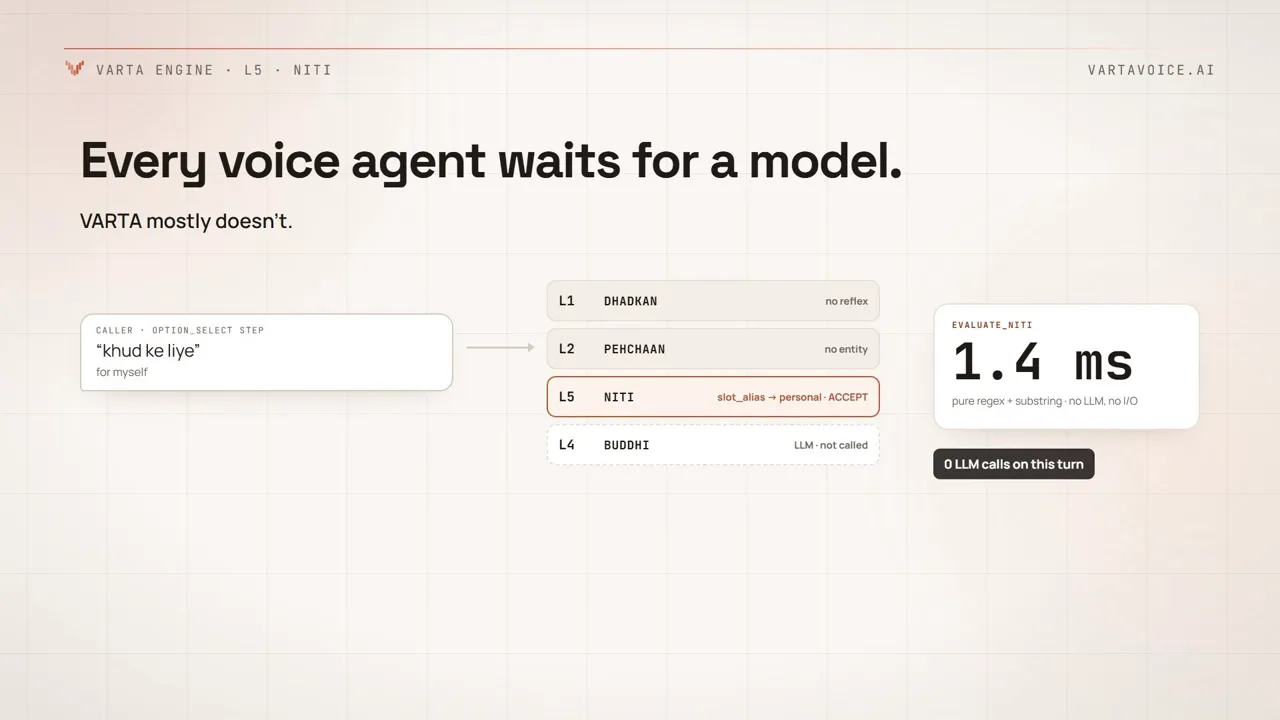
Layer 5 · 1 min
NITI: the rule engine inside VARTA
Every voice agent waits for a language model. VARTA mostly does not. NITI resolves a turn by rule in under two milliseconds, with the LLM as the last resort.
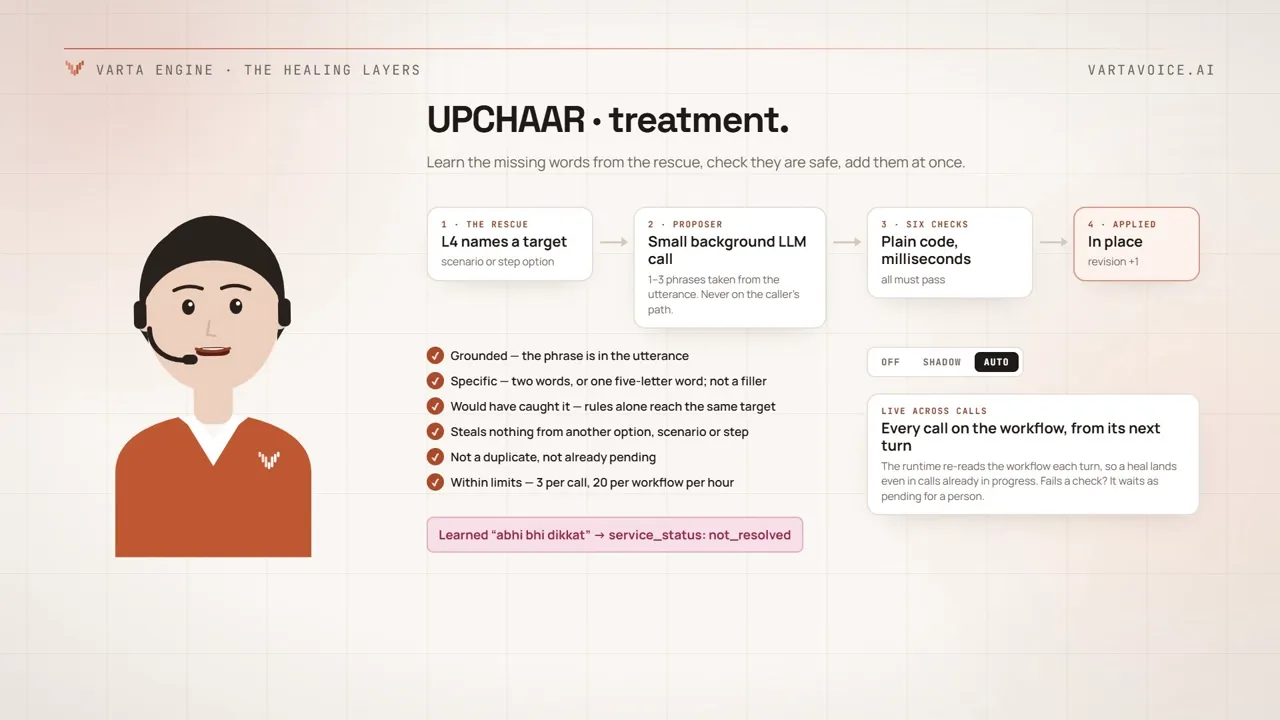
UPCHAAR and SHALYA · 2 min
How VARTA heals itself
Most voice agents stay as smart as the day they were written. VARTA’s two healing layers learn from every LLM rescue and propose structural fixes, checked before anything goes live.
Launch film · 24 s
Introducing VARTA
A voice-agent platform with a visible cost ledger: seven explicit layers, cached audio for repeated phrasing, and only the turns that need reasoning reach an LLM.